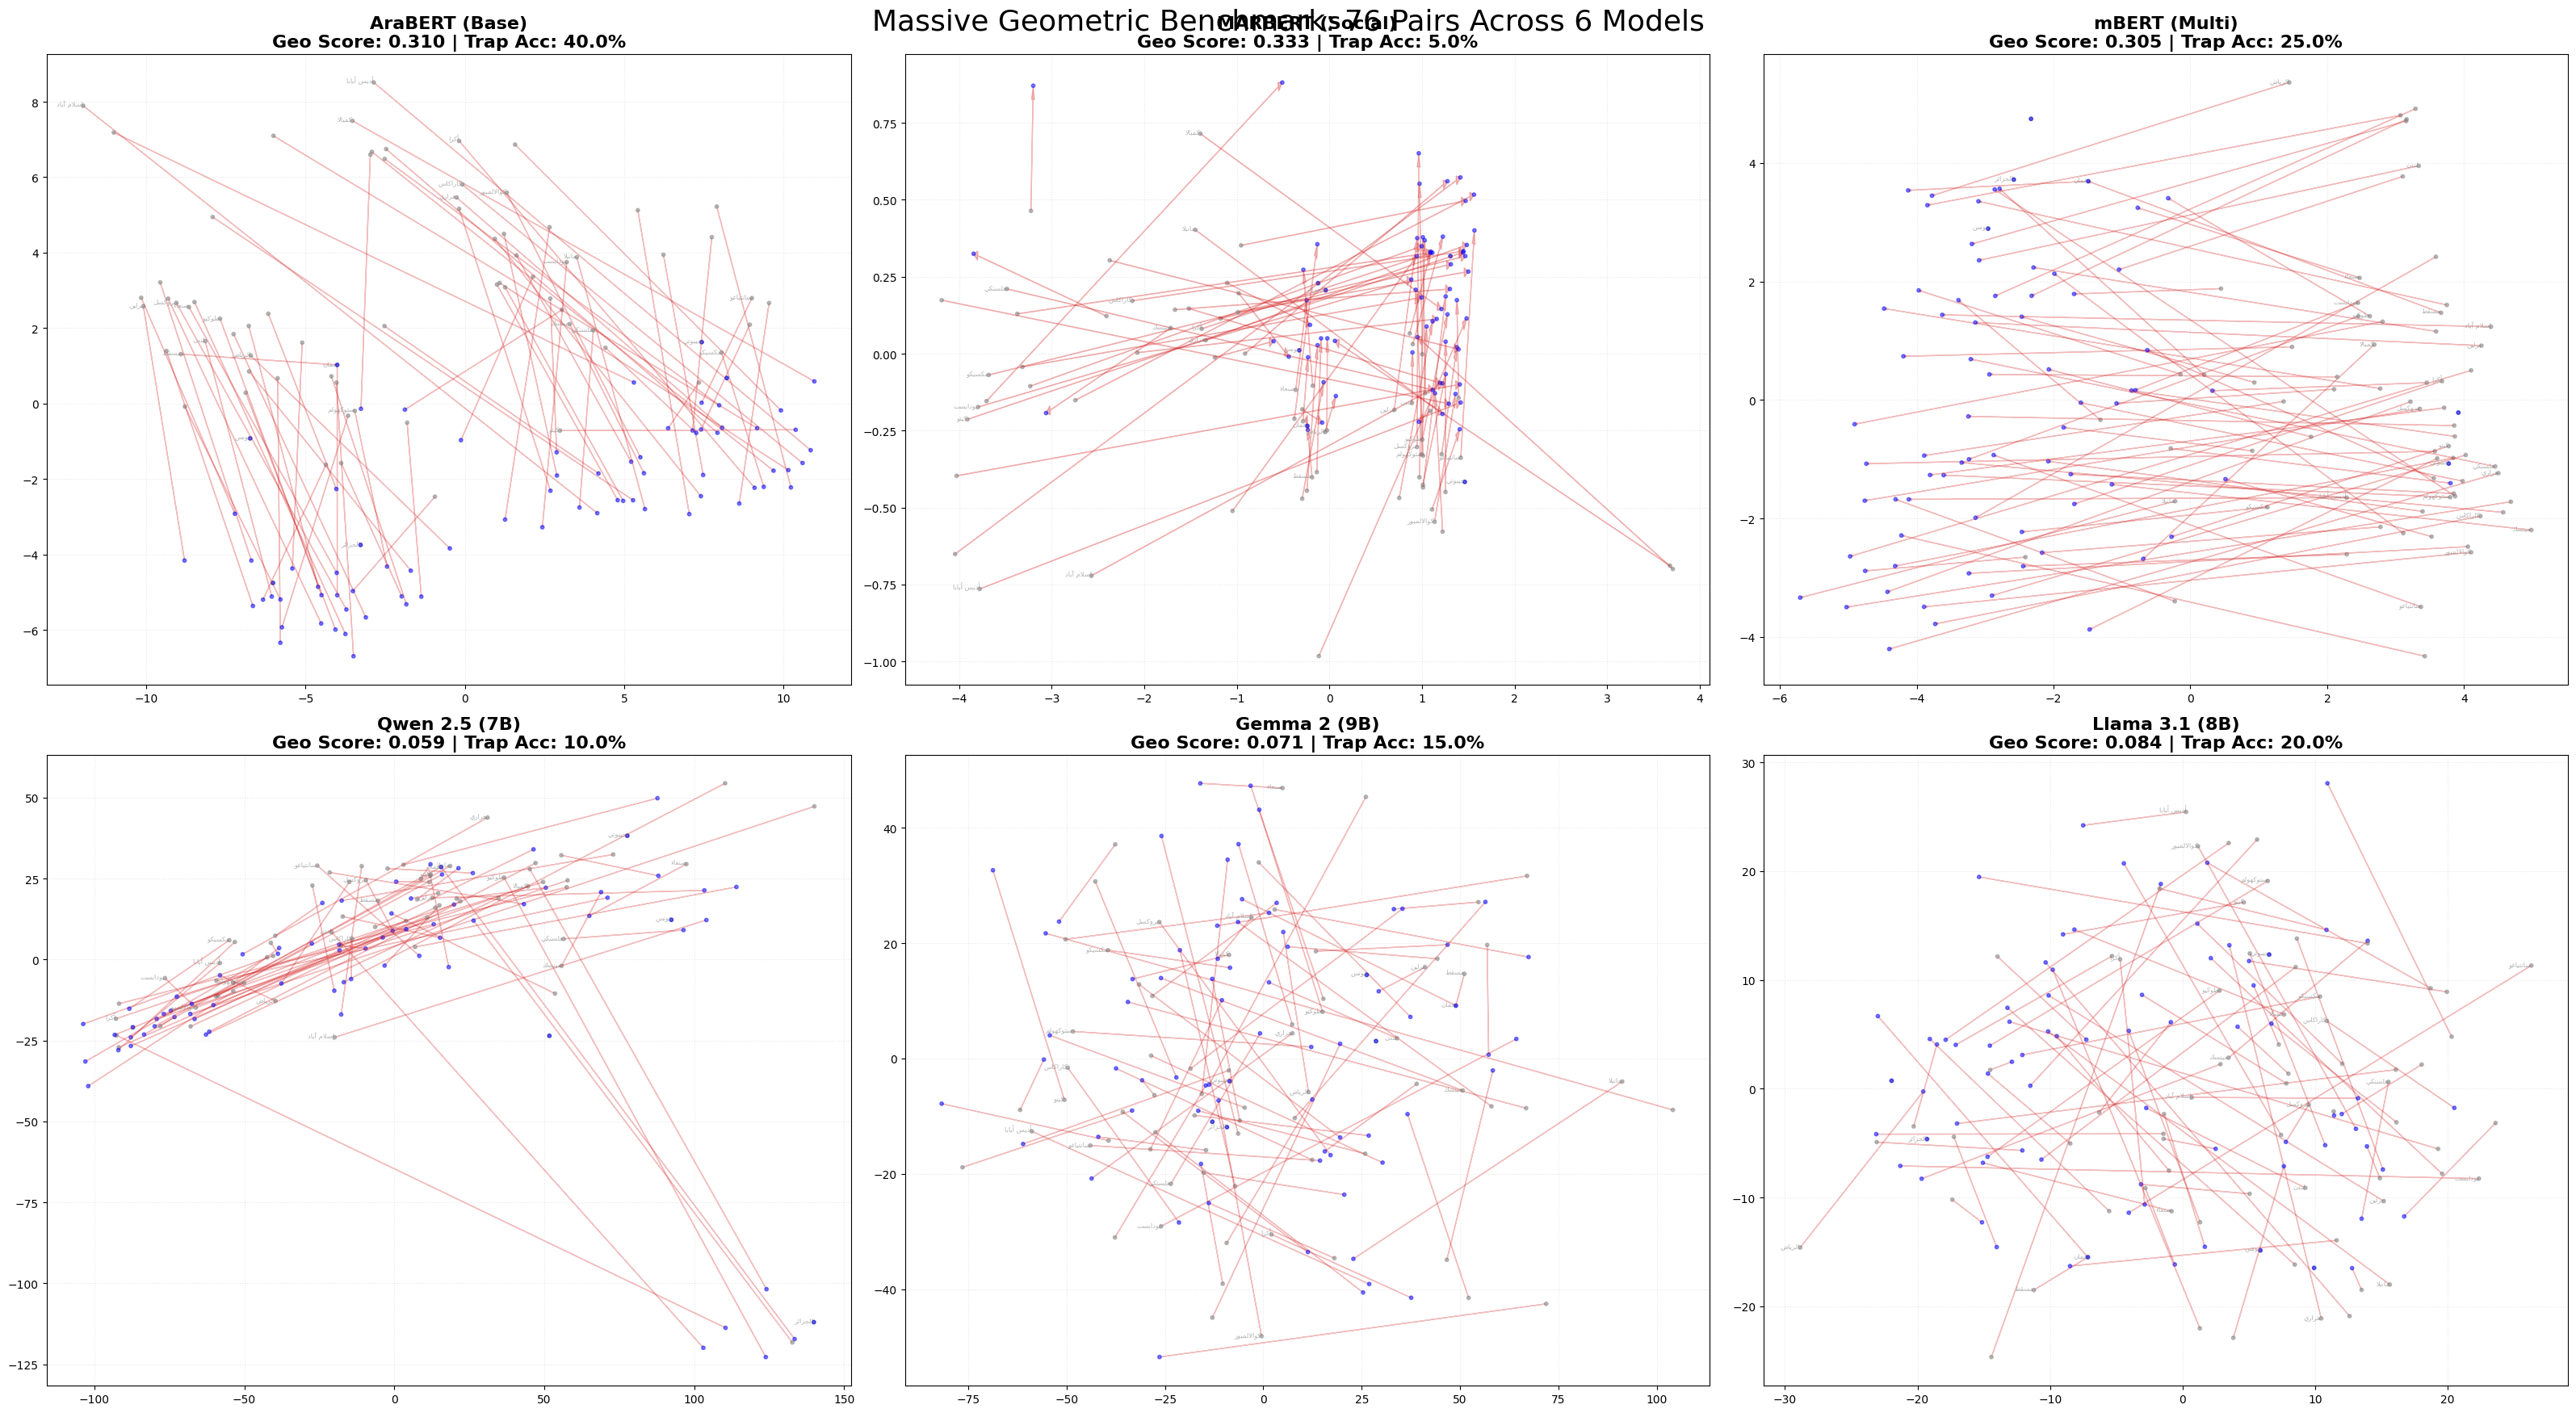
This study challenges the prevailing assumption that decoder-only Large Language Models (LLMs) supersede traditional encoder-based models in all NLP tasks.
Research Questions
- Do modern LLMs maintain linear substructures for analogical reasoning in Arabic?
- Can these models distinguish between semantic intent and lexical attributes when presented with adversarial traps?
Methodology
- Global Geo-Dataset (N=84): Country-Capital pairs across Arab World, Europe, Asia/Americas, and Africa
- Adversarial Trap Dataset (N=20): "Riddles" designed to exploit surface-level lexical overlaps
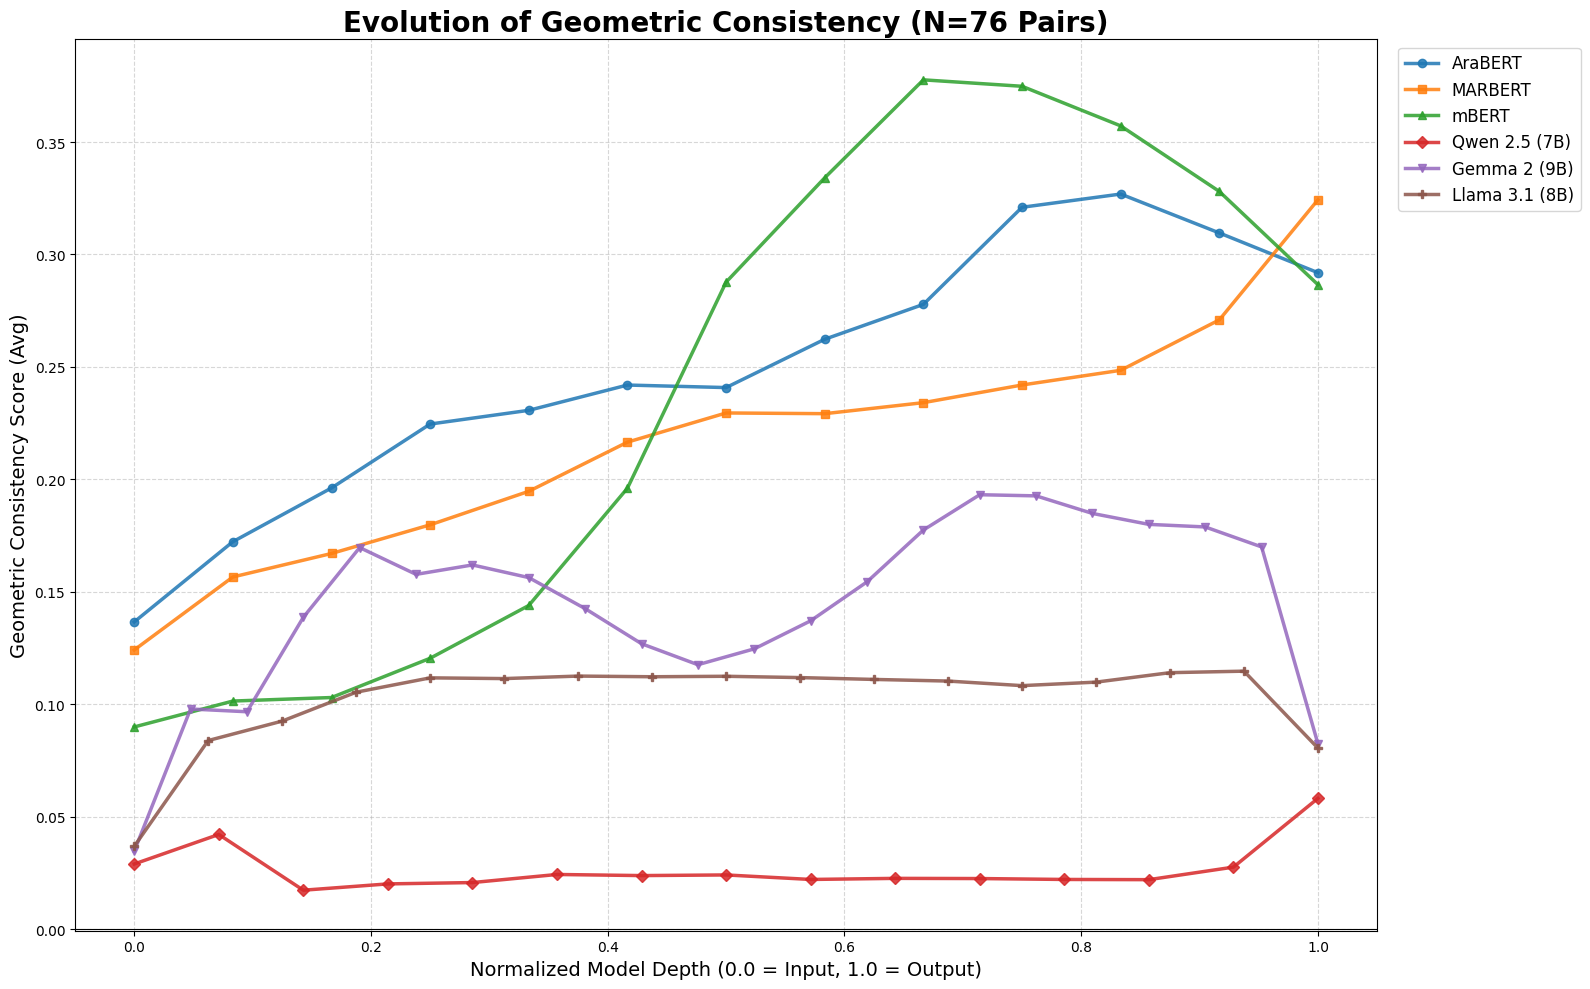
- Layer-wise probing of all models from input to output
Key Results
| Model | Type | Geo Score | Safety Gap |
|----------|---------|-----------|------------|
| AraBERT | Encoder | 0.307 | +0.006 ✓ |
| MARBERT | Encoder | 0.336 | -0.014 |
| mBERT | Encoder | 0.302 | -0.048 |
| Gemma 2 | Decoder | 0.075 | -0.052 |
| Qwen 2.5 | Decoder | 0.054 | -0.053 |
| Llama 3.1| Decoder | 0.082 | -0.099 ✗ |
Conclusion: AraBERT (110M params) is the only model with a positive safety gap, outperforming all tested LLMs (up to 9B parameters) for Arabic semantic retrieval. Decoder LLMs destroy vector geometry in their final layers due to the next-token prediction objective.
تتحدى هذه الدراسة الافتراض السائد بأن نماذج اللغة الكبيرة الحديثة تتفوق على النماذج المتخصصة القائمة على التشفير في جميع مهام معالجة اللغة الطبيعية.
أسئلة البحث
- هل تحافظ نماذج اللغة الكبيرة الحديثة على البنى الهندسية الخطية للتفكير القياسي في اللغة العربية؟
- هل تستطيع هذه النماذج التمييز بين القصد الدلالي والسمات المعجمية عند مواجهة فخاخ خصومية؟
المنهجية
- مجموعة بيانات جيو-عالمية (N=84): أزواج دولة-عاصمة عبر العالم العربي وأوروبا وآسيا وأفريقيا
- مجموعة الفخاخ الخصومية (N=20): ألغاز مصممة لاستغلال التداخلات المعجمية السطحية
النتائج الرئيسية:
AraBERT بـ110 مليون معامل هو النموذج الوحيد بفجوة أمان إيجابية، متفوقاً على جميع نماذج اللغة الكبيرة المختبرة (حتى 9 مليار معامل) في الاسترجاع الدلالي العربي. تُدمر نماذج المفككة هندسة المتجه في طبقاتها الأخيرة بسبب هدف التنبؤ بالرمز التالي.